AI Chatbot Development Services: Insurance Case Study
YlogX Team · 2026-08-26
A claims assistant that refuses coverage questions. See how AI chatbot development services grounded answers in policy wordings and made refusal a feature.
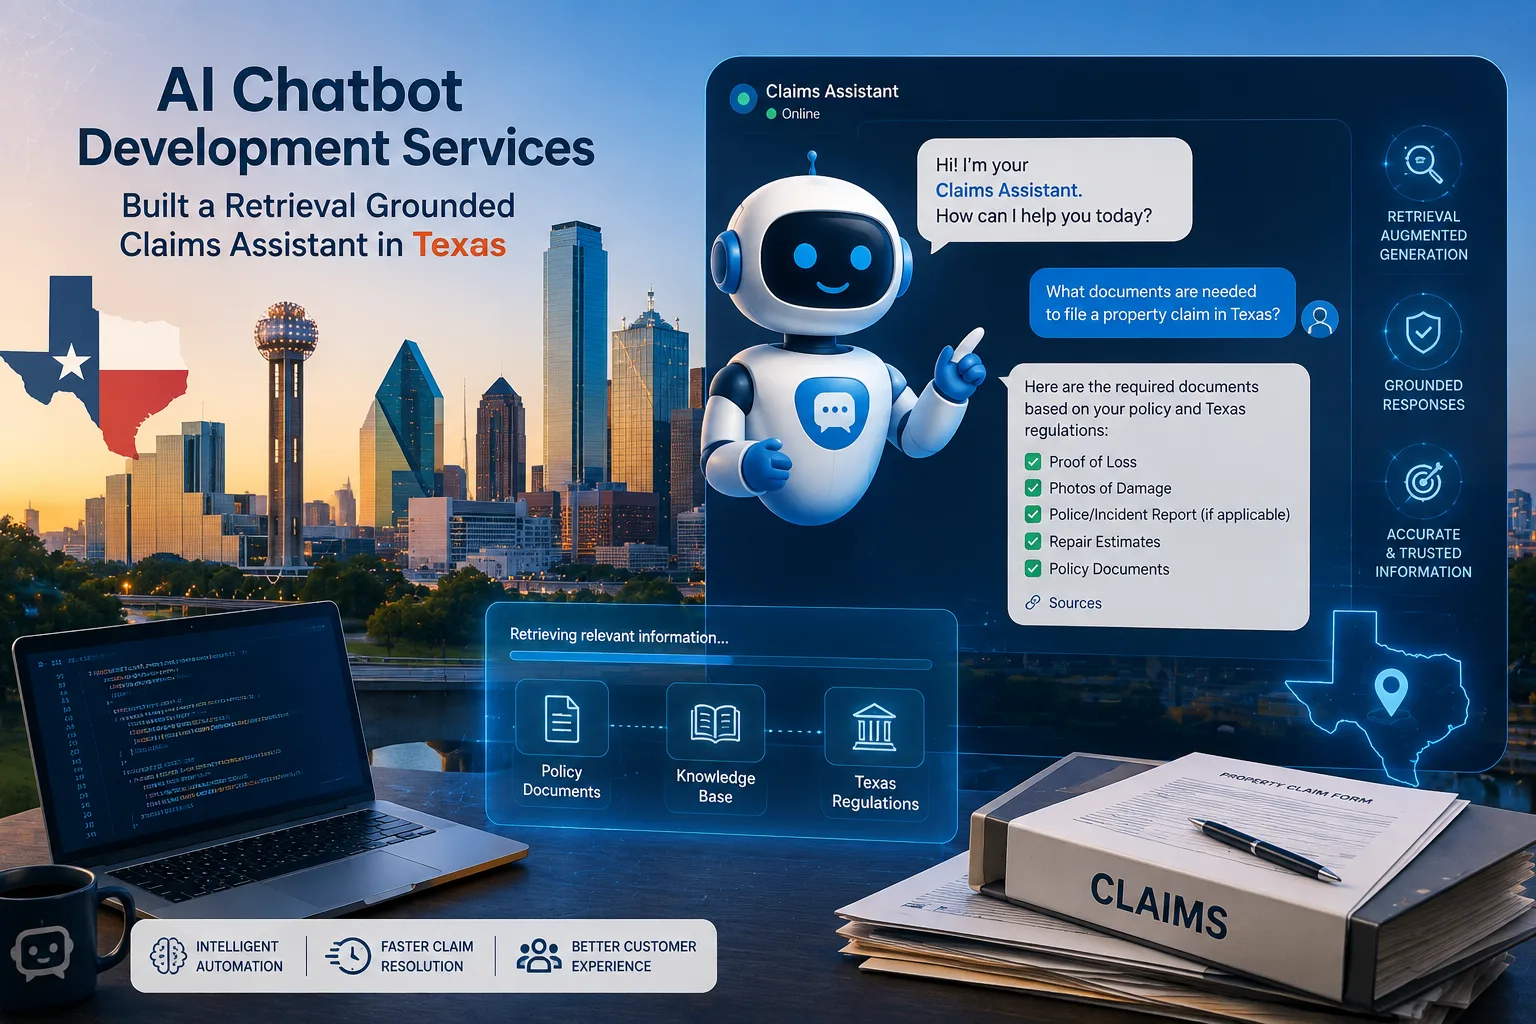
Summary. AI chatbot development services delivered an internal claims assistant for a regional North Texas insurer that refuses coverage determinations by design, grounds every answer in cited policy passages, and is projected to cut document search time by 30–40%.
Executive Summary
AI chatbot development services delivered an internal claims assistant for a regional insurer operating out of North Texas. Handlers were losing significant time hunting through policy wordings, endorsements and internal handling manuals to answer routine procedural questions. The assistant answers those questions and refuses the ones it must not touch.
The single most important design decision was what the system will not do. It does not make or suggest coverage determinations, and it declines those questions explicitly rather than attempting a helpful approximation.
Answers are grounded in retrieved passages from the insurer own documents. Every response cites the document, the version and the section it came from.
Retrieval combines keyword and dense search with a reranking step, which mattered because endorsements modify base policy wordings in ways that pure semantic similarity handles poorly.
Projected outcomes include an estimated 30 to 40 percent reduction in handler time spent searching documents and an estimated 15 to 20 percent reduction in internal escalations to senior handlers on procedural questions. Both figures are modeled.
Handlers searching PDFs instead of handling claims? Talk to us.
Client Overview
The client is a regional property and casualty insurer writing personal and small commercial lines across several southern states, with claims operations based in the Dallas and Fort Worth area.
The claims team runs to a few hundred handlers across first notice of loss, adjusting and complex claims, with a smaller technical unit handling escalations.
Document sprawl is the defining operational feature. Base policy wordings vary by state and by product, and endorsements modify them extensively.
Internal handling manuals, bulletins and procedural updates accumulate alongside. A handler answering a routine question may need to consult three separate documents to be certain.
Turnover in the handler population is meaningful, and new joiners take months to become confident. That ramp time was the business problem behind the request, more than raw handling speed.
Business Challenges
The insurer had already tried a general purpose assistant on a subscription model. It was withdrawn after three weeks because it answered coverage questions confidently and wrongly. That failed attempt shaped the brief more than anything else, and it made the team appropriately sceptical.
Why did the previous assistant have to be withdrawn?
Because it had no grounding. It answered from general knowledge of insurance rather than from the insurer own wordings, which differ from generic practice in material ways.
It also had no concept of scope. Asked whether a particular loss was covered, it produced a fluent and confident answer with no basis in the actual policy.
A senior handler spotted the pattern during informal use and escalated it. Nothing had reached a customer, which was a matter of timing rather than design.
The withdrawal left a legacy of scepticism that turned out to be useful. Nobody in the claims organisation was inclined to accept a demonstration at face value.
Why is retrieval on policy documents harder than it looks?
Because endorsements modify base wordings, sometimes reversing them, and the modification sits in a different document from the clause it changes.
Semantic similarity retrieves the base clause reliably and the endorsement unreliably, because the endorsement text often shares little vocabulary with the question.
Effective dates compound the problem. The correct answer depends on which version was in force at the date of loss, which is metadata rather than content.
State variation adds a third axis. The same product wording differs across states, and retrieving the wrong state version produces an answer that is fluent and wrong.
What was the document search actually costing?
Handlers estimated they spent a meaningful share of each day locating the right passage rather than assessing the claim in front of them.
Escalations to the technical unit were frequently procedural rather than genuinely complex, consuming senior capacity on questions with documented answers.
New joiner ramp time was the larger cost. Confidence comes from knowing where things are, and that knowledge was distributed unevenly across the floor.
None of this was measured before the engagement. Establishing a baseline through observation and handler diaries was part of the assessment phase.
Why could this not be solved with better search?
It partly could, and a portion of the eventual value does come from better retrieval rather than from generation. But handlers ask questions, not keyword queries. A question about notice requirements after a water loss does not map cleanly onto the vocabulary used in the wording.
Search also returns documents. A handler still has to read several pages to extract the answer, which is where most of the time actually goes. The generation step earns its place by extracting and stating the answer from retrieved passages, provided it is constrained to those passages and cites them.
Tried a general assistant and withdrawn it? Read more about our approach at our generative AI capability.
Business Objectives
The claims leadership brief had one hard boundary and three objectives. The boundary was that the system must never appear to make a coverage decision.
Why is refusal treated as the primary requirement?
Because a coverage determination is a regulated decision with consequences for the policyholder and for the insurer, and it belongs to a person. An assistant that approximates one, even accurately most of the time, creates exposure that no efficiency gain would justify.
So scope classification runs before retrieval. A question seeking a coverage determination is refused with an explanation and a pointer to the escalation route. Refusal accuracy is measured on every release alongside answer quality, and a drop in refusal accuracy blocks a release the same way a drop in groundedness would.
What operational outcomes were wanted?
Less handler time spent locating passages, which was the most visible cost and the easiest to observe directly. Fewer procedural escalations to the technical unit, freeing senior capacity for genuinely complex claims. Shorter ramp time for new joiners, which leadership considered the largest long term prize given turnover. Consistency of procedural answers across the floor, since variation between handlers on documented procedure was a known quality issue.
Leadership also wanted a measurable release process, having been burned once by a tool that behaved well in a demonstration and badly in production.
What defined success for this engagement?
Groundedness measured against a labelled golden set built by the technical unit, not by the delivery team, above an agreed threshold. Refusal accuracy on coverage seeking questions above a higher threshold still, tested with adversarial phrasings. Handler adoption sustained past the first month, since novelty use tells you nothing about value. And a release process that blocks deployment when either measure drops, which was built before the first release rather than after an incident.
Success explicitly did not include answering more questions. A system that answers fewer questions correctly was preferred to one that answers everything plausibly.
Need an assistant that knows what not to answer? Start a conversation.
Solution Strategy
The design started from the refusal case and worked outward. That ordering is unusual and it produced a system the claims organisation was willing to trust. Delivery used a YlogX solution accelerator for the retrieval and evaluation scaffolding, adapted to insurance document structure.
How do AI chatbot development services handle question scope?
A classifier runs on every question before retrieval, sorting it into procedural, informational or coverage seeking. The training set was assembled from real handler questions labelled by the technical unit, including deliberately ambiguous phrasings.
Coverage seeking questions are refused with a short explanation and the escalation route, never with a partial answer or a hedge. The classifier is tuned to be cautious. A procedural question wrongly refused costs a handler a few seconds. A coverage question wrongly answered costs considerably more.
How were the documents prepared for retrieval?
Chunking follows document structure rather than fixed token counts, so a clause and its subclauses stay together and retain their heading context. Every chunk carries metadata for document type, product, state, version and effective date range, which is what makes correct filtering possible.
Endorsements are linked to the base clauses they modify during ingestion, so retrieving a base clause also surfaces its applicable endorsements. That linkage was the single most valuable piece of engineering in the project and it required a subject matter session with the technical unit to define.
Why was hybrid retrieval chosen over vector search alone?
Because dense vector search alone retrieved base wordings well and endorsements poorly, which is the exact failure mode the insurer could least afford. Endorsement text often shares little vocabulary with the handler question, while carrying identifiers and defined terms that keyword search matches precisely.
Combining keyword and dense candidates, then reranking against the specific question, improved retrieval quality on the endorsement heavy evaluation subset substantially. The reranking threshold also supplies the second refusal path. When nothing scores well enough, the system says so rather than answering from weak evidence.
How is generation constrained?
The model is instructed to answer only from the supplied passages and to state when those passages do not contain the answer. Citations are generated as structured references to document, version and section, and are verified against the retrieved set before the answer is displayed. A citation that does not resolve to a retrieved passage causes the answer to be suppressed rather than shown with a broken reference.
Personally identifiable information is redacted from queries before they leave the environment, and the redaction is logged for audit.
How was evaluation made rigorous?
A golden set of several hundred questions was built by the technical unit, with correct answers and the passages that support them. Groundedness, answer relevance, retrieval recall and refusal accuracy are scored on every release against that set.
Adversarial phrasings were added deliberately, including coverage questions dressed as procedural ones, which is how handlers actually phrase them under pressure. Weekly sampling of live traffic supplements the golden set, because real questions drift away from any fixed evaluation set within months.
Have endorsements that reverse the clause they sit beside? Read more at our AI consulting capability.
Technologies and Tools Used
Component choices were driven by two constraints. Data residency requirements for policyholder information, and a claims technology team that would own the system after handover.
How was the data and document layer built?
Documents are ingested from the existing document management system on a schedule, with version changes detected and reindexed rather than reloaded wholesale. Structure aware parsing preserves headings, clause numbering and table content, since procedural answers frequently live in tables.
The vector store and keyword index sit inside the insurer cloud tenancy, meeting the residency requirement without a separate negotiation. Ingestion failures are alerted rather than logged quietly, because a silently stale index produces answers that were correct last quarter. Reindexing runs incrementally on version change, so a bulletin issued on a Friday is retrievable on the Monday without a full rebuild.
Which model components were used?
An embedding model for dense retrieval, a cross encoder for reranking, and a general purpose language model for constrained generation. Model choice is configurable rather than hard coded, since the field moves quickly and the insurer wanted the option to change without redevelopment.
The scope classifier is a small supervised model rather than a prompt, because it runs on every request and its behaviour must be stable across model updates. Nothing about the architecture is exotic. The engineering value sits in endorsement linkage, metadata filtering and the evaluation harness.
What controls and logging were implemented?
Every exchange is logged with the question, the retrieved passages, the generated answer, the citations and any handler feedback. Prompt injection defences cover document sourced instructions, since ingested content is not fully trusted even when it comes from internal systems.
Access follows existing claims system permissions, so a handler cannot retrieve documents they would not otherwise be able to open. Retention is set to match the insurer existing claims documentation policy rather than being decided separately by the project. Handler feedback is stored with the exchange rather than separately, so a reported problem arrives with the retrieved passages that caused it.
How does the evaluation harness run?
As a stage in the deployment pipeline. A release that fails any threshold does not deploy, and the failing cases are reported with their retrieved passages. Weekly live traffic sampling runs on a schedule, with results reviewed by the technical unit rather than by the delivery team.
Drift on retrieval recall is the earliest warning signal and is watched most closely, since it usually indicates a document set change. Handler thumbs down feedback routes into a queue that the technical unit triages, and confirmed problems become new golden set entries.
Implementation Process
The engagement ran about nineteen weeks. Document preparation and endorsement linkage consumed more of it than model work, which is the usual shape of a serious retrieval project. A narrow first scope, one product line in one state, made the endorsement problem tractable before it was generalised.
How was the first scope chosen?
One personal lines product in one state, chosen because the technical unit knew its wordings thoroughly and could build a reliable golden set quickly. That narrow scope also kept the endorsement linkage exercise finite, since defining the linkage rules required subject matter time that could not be rushed.
Handler questions for the golden set were drawn from real escalation records rather than invented, which surfaced phrasings nobody would have written. Scope widened to two further products from week twelve, once linkage rules and evaluation thresholds had proven stable.
How was the golden set constructed?
The technical unit wrote questions and correct answers, and identified the supporting passages, working from real escalation history. Deliberately adversarial items were added, including coverage questions phrased to sound procedural, which is how they arrive in practice.
The delivery team did not author golden set items, so evaluation could not drift toward what the system happened to do well. Construction took about three weeks of technical unit time spread across the engagement, which was agreed and protected at kickoff. It is a living asset rather than a fixed artefact, and confirmed handler complaints become new entries as they are triaged.
How was the system piloted with handlers?
With twelve handlers across experience levels for four weeks, running alongside their normal process rather than replacing any step. Feedback was collected in the tool and in weekly sessions, and the weekly sessions consistently surfaced issues the in tool feedback did not.
New joiners used it differently from long serving handlers, asking broader questions, which led to a change in how answers present surrounding context. Two handlers actively tried to make it answer coverage questions. Both attempts were refused correctly, and the attempts became golden set entries.
How was it handed over?
Ownership sits with the claims technology team, with the technical unit owning the golden set and evaluation thresholds. That split matters. Engineering owns the system and subject matter owns the definition of correct, which stops evaluation quietly becoming a technical convenience.
Documentation covers ingestion, linkage rule maintenance, threshold changes and the release gate, written for the team that inherited it. A document change during the final month was ingested and reindexed by the client team without assistance, which was the handover acceptance test.
Wondering what a narrow first scope would prove for you? Talk to us.
Business Results
The figures below are estimated business outcomes, modeled on the engagement scope and on published benchmarks. They are projections rather than audited client results. Evaluation measurements taken during the work are reported as observations. Coverage is three product lines at the point of handover, so results apply to questions within that scope.
What did evaluation actually measure?
Refusal accuracy on coverage seeking questions was the highest scoring measure and the one held to the strictest threshold, including on adversarial phrasings.
Groundedness against the golden set improved materially once hybrid retrieval and reranking replaced dense search alone.
Retrieval recall on the endorsement heavy subset was the measure that separated the two retrieval approaches most clearly.
Two pilot handlers deliberately attempted to obtain coverage answers and both attempts were refused, which the claims leadership treated as the decisive test.
What is projected for handler productivity?
Time spent searching policy documents is projected to fall by an estimated 30 to 40 percent for questions within the covered scope.
Procedural escalations to the technical unit are projected to reduce by an estimated 15 to 20 percent, releasing senior capacity for complex claims.
Consistency of procedural answers across the floor is expected to improve, though the insurer has no baseline measure for it and no figure is offered.
New joiner ramp time is expected to shorten, which leadership considers the largest long term benefit, but a credible estimate needs a full intake cohort.
What changed for handlers day to day?
Answers arrive with the passage and the document version attached, so a handler verifies rather than trusts. That verification step is fast and it is the reason adoption held past the pilot. Handlers described the citations as the feature that made it usable.
Refusals are accepted without frustration, because the refusal explains itself and points to the escalation route. New joiners use it more broadly than long serving handlers, asking orientation questions they would previously have taken to a colleague. The escalation route is also clearer than before, because the refusal message names it explicitly rather than leaving a handler to guess.
What changed structurally?
Endorsement to clause linkage now exists as structured data, which has value beyond the assistant and is already being used elsewhere.
The golden set is a durable asset owned by the technical unit, and it grows from confirmed handler feedback.
A release gate blocks deployment when groundedness or refusal accuracy drops, which was built before the first release rather than after an incident.
The claims technology team ingests document changes and maintains linkage rules without assistance.
Document metadata quality improved as a side effect, since gaps in state and effective date fields had to be corrected before retrieval could filter on them.
Want refusal accuracy tested on every release? Contact us.
Lessons Learned
Designing from the refusal case outward was the decision that made everything else possible. It is also the decision most teams skip.
What surprised the client most?
That the previous assistant had failed on grounding rather than on model quality—the model had been capable and completely unanchored. That dense vector search alone handled endorsements so poorly, given how well it handled base wordings in early demonstrations. That handlers valued citations above answer quality—verification turned out to matter more than fluency. That new joiners used the assistant differently, which changed a product decision about how much surrounding context an answer should include. It also surprised leadership that the strongest measured result was refusal accuracy, which is a measure of restraint rather than of capability.
What worked better than expected?
Building the golden set inside the technical unit rather than in the delivery team kept the definition of correct outside engineering control. Adding adversarial coverage questions early paid off—two pilot handlers attempted exactly those attacks unprompted, and the system was ready. Endorsement to clause linkage was the hardest engineering task and it produced an asset the insurer now uses beyond this project. Weekly pilot sessions consistently surfaced issues that in tool feedback did not, which is a pattern worth planning for rather than discovering.
What would be done differently next time?
Endorsement linkage rules would be defined before any retrieval approach is evaluated, since the evaluation result depends heavily on them. The baseline measurement of handler search time would be instrumented rather than estimated from diaries, which limits how confidently the improvement can be stated. Live traffic sampling would start during the pilot rather than at go live, since pilot traffic is the most informative and it was not sampled systematically. The new joiner use case would be treated as a distinct persona from the start rather than discovered during the pilot.
What should other insurers check first?
Ask whether any existing assistant can be induced to answer a coverage question. If nobody has tried, that test is the first thing to run. Check whether endorsements are linked to the clauses they modify anywhere in your systems—in most insurers that relationship exists only in people's heads. Check whether document metadata carries state, product, version and effective date—retrieval without those filters returns confident answers from the wrong wording. Ask who would own the definition of a correct answer. If the answer is the vendor, evaluation will drift toward what the system does well.
Frequently Asked Questions
What do AI chatbot development services actually build for an insurer?
For internal claims use, typically a retrieval grounded assistant rather than a conversational agent. Answers are generated only from retrieved passages of the insurer own policy wordings, endorsements and handling manuals, with citations to document, version and section. Scope classification and refusal behaviour are usually more important design work than the conversational surface.
Why should an assistant refuse coverage questions?
Because a coverage determination is a regulated decision with consequences for the policyholder and the insurer, and it belongs to a person. An assistant that approximates one, even accurately most of the time, creates exposure no efficiency gain justifies. Refusal should be explicit, explained, and tested on every release alongside answer quality.
What is retrieval augmented generation and why does it matter here?
It means the model answers from passages retrieved from your own documents rather than from general training knowledge. It matters in insurance because policy wordings differ from generic practice, vary by state and product, and are modified by endorsements. Without grounding, a fluent and confident answer can have no basis in the actual policy.
Why is hybrid retrieval better than vector search alone?
Dense vector search retrieves base wordings well and endorsements poorly, because endorsement text often shares little vocabulary with the handler question while carrying identifiers and defined terms that keyword search matches precisely. Combining both candidate sets and reranking against the specific question improved quality substantially on the endorsement heavy evaluation subset.
How do you stop the assistant answering from the wrong policy version?
With metadata rather than content. Every chunk carries document type, product, state, version and effective date range, and retrieval filters on those before ranking anything. Without those filters a system will confidently return the correct clause from the wrong state or the version that was superseded two years ago.
How is groundedness measured?
Against a labelled golden set of questions with correct answers and the passages that support them, scored on every release. Groundedness, answer relevance, retrieval recall and refusal accuracy are all measured. The golden set should be built by subject matter staff rather than the delivery team, otherwise evaluation drifts toward what the system happens to do well.
What is a release gate and why build it early?
It is a stage in the deployment pipeline that blocks a release when any evaluation threshold is not met, reporting the failing cases with their retrieved passages. Building it before the first release rather than after an incident is what makes quality a property of the system rather than a promise. It applies equally to refusal accuracy and groundedness.
How long does an engagement like this take?
This one ran about nineteen weeks. Document preparation and linking endorsements to the clauses they modify consumed more time than every model decision combined. A narrow first scope, one product line in one state, made the linkage problem tractable before it was generalised to further products.
Do handlers actually trust an AI assistant?
They trusted this one because every answer carries the passage and document version it came from, so verification is fast. Handlers described citations as the feature that made the tool usable, ranking it above answer quality. Refusals were accepted without frustration because each refusal explains itself and points to the escalation route.
Are the results in this case study real client figures?
The evaluation observations, including the refused adversarial attempts during the pilot, are from the engagement. The percentage improvements are estimated business outcomes modeled on scope and published benchmarks, and every one is labelled as projected. Client identity and commercially sensitive details are withheld, and nothing here is regulatory or insurance advice.
Conclusion
AI chatbot development services succeeded here because the design started from what the system must never do. A previous general purpose assistant had been withdrawn after three weeks for answering coverage questions confidently and without basis, and that failure set the brief. Scope classification runs before retrieval, coverage seeking questions are refused with an explanation, and refusal accuracy is tested on every release with adversarial phrasings drawn from how handlers actually ask under pressure.
The engineering that mattered most was not the model. It was linking endorsements to the clauses they modify, carrying state, product, version and effective date as retrieval metadata, and replacing dense vector search with hybrid retrieval and reranking so that an endorsement reversing a base clause is actually found.
Projected outcomes include an estimated 30 to 40 percent reduction in document search time and an estimated 15 to 20 percent reduction in procedural escalations, both modeled rather than measured. What handlers actually praised was none of that. It was the citation on every answer, which let them verify in seconds instead of trusting.
Every figure in this case study is an estimated business outcome, modeled on the engagement scope and on published benchmarks — not audited client data. Client identity and commercially sensitive details have been withheld. Nothing here is regulatory, insurance or legal advice.